A Lightweight Vision-Language Model for Disaster Image Summarization

International Conference · 2026

A Lightweight Vision-Language Model for Disaster Image Summarization

Keywords

Semantic CommunicationDisaster ResponseVision-Language ModelEdge InferenceDR-IoTImage Captioning

Hibiki Yoshizaki , Akira Uchiyama , Akihito Hiromori , Mineo Takai , Hirozumi Yamaguchi

2026 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops), PerconAI 2026, pp. 1203–1208

DOI: 10.1109/PerComWorkshops68308.2026.11585419

Research Note

Immediately after a large-scale disaster, response agencies must obtain accurate situational awareness quickly. Images of on-site conditions are a valuable source of information, but their size makes real-time aggregation from many locations impractical when communication infrastructure is degraded. Disaster-ready wide-area wireless systems such as LPWA and DR-IoT provide only tens of kbps — enough for text but not raw images.
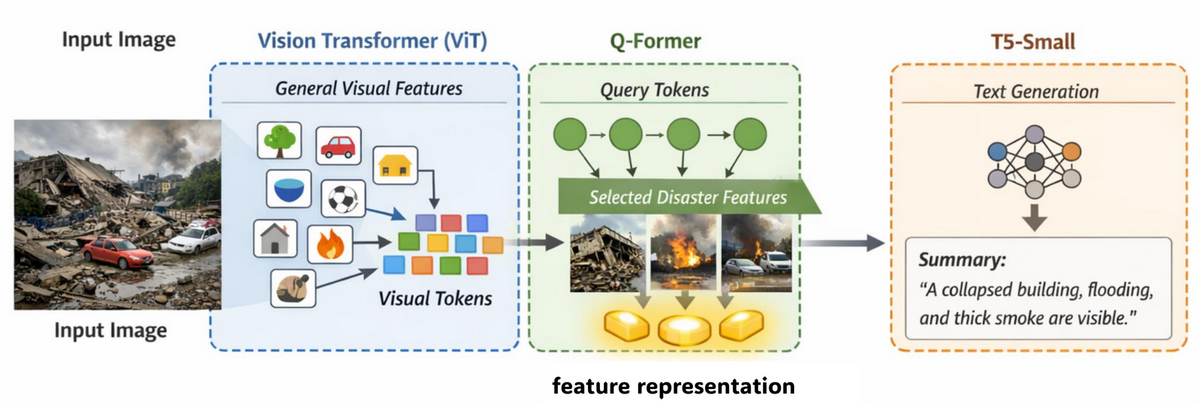
Overview of the proposed lightweight vision-language model

We propose a two-stage reporting scheme: each edge device captures local scenes, summarizes them on-device into concise text, and transmits only the text as a compact proxy. The emergency operations center can then selectively request high-resolution images for scenes that require deeper analysis, allocating bandwidth and personnel where they matter most.

At the core of this system is a lightweight vision–language model designed to run on small edge devices. Targeted at disaster scene summarization, it is evaluated against existing lightweight captioning baselines in terms of output quality, model size, and latency. Results show that our model achieves practical latency on IoT-class devices while matching or exceeding baselines on disaster-domain summarization, demonstrating its suitability for real-world deployment.
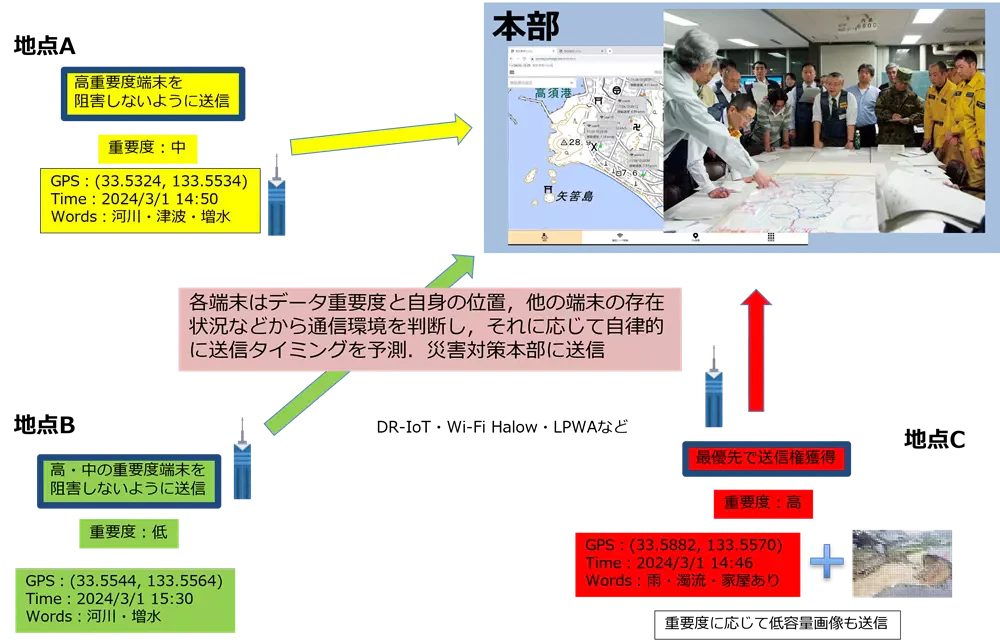
セマンティック通信による多端末連携型の状況理解と消防システムへの適用

セマンティック通信による多端末連携型の状況理解と消防システムへの適用

Ministry of Internal Affairs and Communications (MIC) FORWARD
デジタルインフラ構築部門

A Simulation-based Framework for Dynamic Light Pollution Prediction in Urban Air Mobility

Ying Chieh Wang, Tatsuya Amano, Hirozumi Yamaguchi

2026 IEEE International Conference on Smart Computing (SmartComp), Messina, Italy, 2026, pp. 136-143

DOI 10.1109/SmartComp69968.2026.00029

Urban Air MobilityUAM +2

Environment-Aware Distributed Scheduling for Emergency LoRa Networks

Yuto Inaba, Tatsuya Amano, Akihito Hiromori, Hirozumi Yamaguchi

2026 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops), SPT-IoT 2026, pp. 1366–1371

DOI 10.1109/PerComWorkshops68308.2026.11585469

Disaster CommunicationLoRa +4

Physics-Integrated Deep Learning for Urban Landslide Prediction

Ren Ozeki, Hamada Rizk, Hirozumi Yamaguchi

2026 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops), URBSENSE 2026, pp. 1094–1099

DOI 10.1109/PerComWorkshops68308.2026.11585337

Landslide PredictionPhysics-Integrated Learning +3

A Simulation Framework for Precision Formation Flying of Massive Satellite Swarms

Tatsuya Amano, Akihito Hiromori, Hirozumi Yamaguchi, Sumio Morioka

2026 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops), PerVehicle , pp. 230–235

DOI 10.1109/PerComWorkshops68308.2026.11585321

Satellite Formation FlyingDistributed Simulation +4

Ray-Tracing-Driven Pattern-Based Vehicle Recognition in ISAC Radar

Heetae Jin, Akira Uchiyama

2026 IEEE International Conference on Pervasive Computing and Communications Workshops and other Affiliated Events (PerCom Workshops), PerRad 2026, pp. 328–333

DOI 10.1109/PerComWorkshops68308.2026.11585327

ISACBeyond 5G +4

A Questionnaire-Only Counterfactual Machine Learning Approach to Assess the Spatial Impact of Green Mobility Vehicles in Urban Parks

Rami Naeem, Srikant Manas, Tatsuya Amano, Hirozumi Yamaguchi

ICDCN 2026 Workshop: IWNDSC2026

DOI 10.1145/3737611.3776620